Author2026 – present
Every app, script and agent I run needs a model from somewhere. Some are on my own machines, some are in the cloud. Without a plan, each of them ends up with its own keys, its own settings and its own way of failing.
The Inference Gateway is my answer to that. It’s one front door. Apps ask for what they need, and the gateway takes care of the rest.
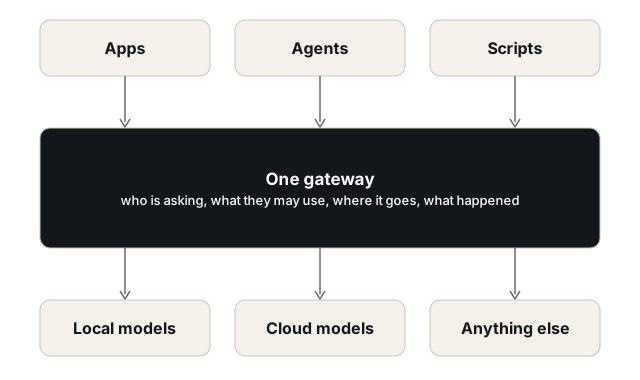
Behind it I plug in whatever answers best: local models on my own machines, my decision engine Zig, and cloud models when I want them.
Why the idea is worth having
- Apps stay simple. They don’t need to know which model answers or where it lives.
- Swapping is cheap. A new model or provider is a change in one place, not in every app.
- Limits and access in one spot. Each app gets its own identity and its own boundaries, so one noisy experiment can’t use up everything.
- Things keep working. If one provider is down, there’s another way to answer.
- You can see what happened. A single record of who asked for what makes debugging and cost much less mysterious.
It’s a private project and it runs my own setup, so I won’t go into the internals. The idea applies to anyone running more than a couple of models: put one calm layer between the apps and the models.
If you’re thinking about something similar, I’m happy to talk about it.